What Is Mean Time to Resolution (MTTR) & How to Improve It
Learn what Mean Time to Resolution (MTTR) actually measures, the hidden bottlenecks inflating your times, and how to fix them without ruining service quality.
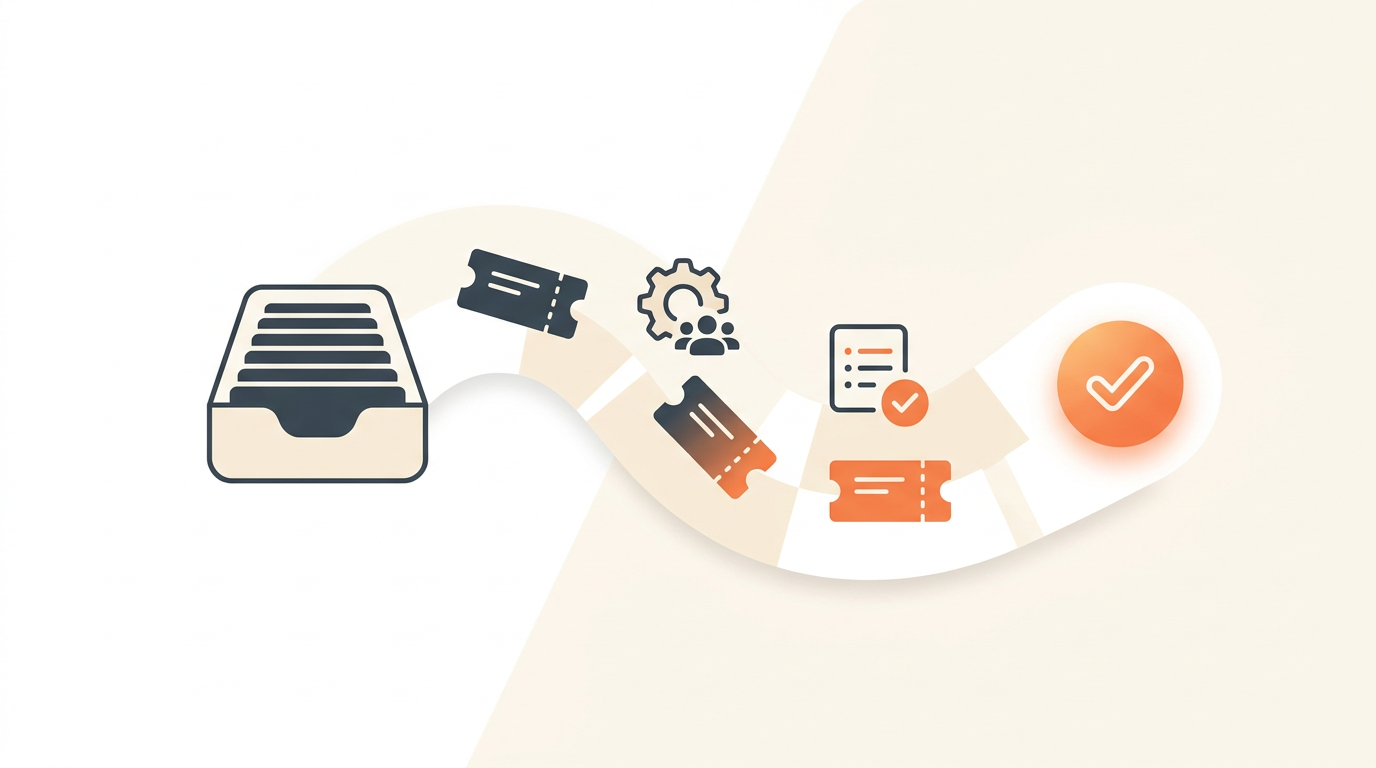
Mean Time to Resolution (MTTR) is the average amount of time it takes your IT or operations team to fully resolve a submitted ticket, calculated from the moment it is logged until the underlying issue is fixed. It serves as a baseline indicator of service desk efficiency and staffing adequacy. However, a lower MTTR only indicates true success if your ticket reopening rates remain flat; slashing resolution times simply by closing unresolved tickets artificially renders the metric entirely useless.
What MTTR Actually Measures (and What It Doesn't)
MTTR tracks the total lifespan of an active support request. In IT service management, "resolution" means the user's problem is eliminated or their request is fulfilled, and normal work can resume. It is distinct from Mean Time to Respond (which only measures how fast you acknowledge the ticket) and Mean Time to Recovery (which focuses specifically on system downtime rather than individual employee requests).
Crucially, MTTR is an average. If you resolve 99 tickets in five minutes each, but one complex infrastructure ticket takes a month, your average will skew higher. This is why experienced IT managers rarely look at MTTR in isolation. They segment it by priority, ticket type, and group. A blanket MTTR metric across an entire organization hides the real story of how your service desk is performing. If you treat a requested software license the same as a massive server outage, your data will tell you nothing actionable.
The Four Hidden Bottlenecks Inflating Your Resolution Times
When service desks struggle with high resolution times, the problem rarely originates from lazy technicians. Long wait times are almost always a symptom of broken workflows, missing context, or structural bottlenecks.
1. The Triage and Routing Delay
In many environments, a ticket sits in a default "Unassigned" queue until a dispatcher reads it, guesses who should handle it, and manually assigns it. This purely administrative step adds hours to the clock before any actual troubleshooting begins. If your MTTR is high but actual touch-time is low, poor routing is your primary culprit.
2. The Blank Form Problem
When employees submit issues via open-ended text fields (or basic emails), they almost never provide the required technical context. An agent must reply asking for asset numbers, error screenshots, or specific software versions. The ticket then stalls, waiting for the user to reply. Incomplete intake forms guarantee a delayed resolution.
3. Approval Workflows Slower Than the Fix
A user requests access to a restricted database. The IT technician knows exactly how to grant it and can do so in two minutes. However, policy dictates that the user's manager must approve it. The ticket sits open for three days waiting for a manager to notice a notification. The technical execution is instantaneous, but the administrative bloat destroys the metric.
4. Siloed Tribal Knowledge
When a complex problem arises, agents often escalate simply because the documentation to fix it lives entirely in the head of a senior engineer. When tier-one agents cannot search for and apply a known fix, tickets bottleneck behind your most expensive, busiest staff members.
How to Calculate Mean Time to Resolution Accurately
Calculating MTTR requires you to define two critical parameters: business hours and pause states. If your team only works 9 AM to 5 PM, Monday through Friday, a ticket opened at 4:30 PM on Friday and closed at 9:30 AM on Monday took one hour to resolve, not 65 hours. If you measure strictly in calendar hours for a local team, your metrics will look disastrous every Monday morning.
The standard formula is: Total time spent resolving tickets during the period / Total number of resolved tickets.
To keep the data honest, you must implement SLA rules that allow agents to pause the clock. When an agent replies to a user asking for more information, the ticket status should change to "Pending User," pausing the resolution timer. The clock only resumes when the user provides the missing details. Without this configuration, your MTTR penalizes your team for an employee's failure to check their inbox.
Step-by-Step: Improving MTTR Without Sacrificing Quality
Lowering your resolution times requires systematic changes to how work enters and moves through your helpdesk. Follow this exact progression to strip out wasted time.
- Eliminate open-ended intake: Replace blank email submissions with a structured Service Catalog. Present employees with a browsable menu of pre-approved requests (e.g., "Request a New Laptop," "Access Salesforce"). This forces the user to provide necessary variables upfront, eliminating the back-and-forth discovery phase.
- Deploy agentic auto-resolution: Not all tickets require human intervention. For common, well-documented employee requests like standard password resets or basic access grants, use an AI agent grounded in your Knowledge Base to process and resolve the request the moment it arrives.
- Automate your triage: Stop manually reading and assigning tickets. Use AI-powered ticket triage to categorize incoming requests by ITIL type, assess the urgency, and apply assignment rules (first-match routing) to push the ticket to the correct group instantly.
- Configure granular SLA pause rules: Audit your helpdesk configuration. Ensure that "Pending User" and "Pending Vendor" statuses actively pause the SLA timers. This gives you a true picture of active resolution time and encourages agents to maintain clean ticket statuses.
- Standardize approval flows: Build approval logic directly into the ticket templates for service requests and changes. When an employee requests a paid software license, the ticket should automatically trigger an approval request to their specific manager without an IT agent needing to act as the middleman.
Illustrative Scenario: Escaping the Shared Inbox Trap
Consider a growing 60-person logistics company that previously managed all employee IT issues through a shared "support@" email inbox. Employees sent vague emails like "My scanner is broken." An IT staff member would eventually see the email, ask which warehouse the user was in, wait for a reply, and then figure out who was on shift there. Average resolution times hovered at several days because of the sheer volume of manual administration.
By transitioning to a structured employee portal with a choice of traditional forms or AI chat intake, they forced employees to specify their location and device type during submission. AI triage read the intake context and immediately routed scanner issues to the specific group managing hardware in that exact region. Without adding any new IT headcount, their resolution times dropped from days to minutes simply by eliminating the manual discovery and routing phases.
Traditional vs. AI-First Resolution Models
The tools you use dictate how fast you can move. Legacy IT systems demand heavy configuration to achieve basic speed, whereas modern systems treat speed as the default.
| Process Phase | Traditional Service Desk | AI-First Service Desk |
|---|---|---|
| Ticket Intake | Users send emails or fill out static, rigid web forms that often lack context. | Users interact via conversational AI or dynamic Service Catalogs that demand context before submission. |
| Triage & Routing | Human dispatchers read tickets and assign them, or brittle keyword rules frequently fail. | AI (like QueAssist) categorizes, prioritizes, and routes the ticket to the correct team upon arrival. |
| Resolution | Agents manually search wikis for fixes, write replies, and execute the steps by hand. | Agentic auto-resolution handles common requests instantly; agents only handle escalations and complex issues. |
| Measurement | Requires manual SLA reporting and complex database queries to separate active from paused time. | Configurable SLA rules per priority automatically track real business hours and pause states. |
The Role of ITIL Ticket Types in Resolution Metrics
You cannot effectively improve MTTR if you dump every unit of work into a single bucket. Good operational hygiene requires separating your workflows into standard ITIL ticket types: Incidents, Service Requests, Problems, and Changes. Each requires a different approach to resolution.
An Incident is an unplanned interruption to a service (e.g., the WiFi is down). Your MTTR goal here should be aggressive, as downtime costs the business money. A Service Request is a user asking for something new (e.g., a new monitor). These should have entirely different, often longer, resolution targets because they may require purchasing or shipping.
Problems represent the root cause of multiple incidents. Resolving a Problem might take weeks of investigation and patching. If you blend Problem tickets into your standard Incident MTTR, your data will look disastrous. Keep them separate. Changes involve modifying the IT environment and often require CAB (Change Advisory Board) approval. Never track Change completion times in the same metric as end-user support resolution.
The Danger of Optimizing for Speed: Common MTTR Mistakes
Optimizing strictly for a lower resolution time often creates perverse incentives. The most common failure mode is agents cherry-picking easy tickets. If technicians are evaluated solely on their individual MTTR, they will aggressively claim simple password resets and ignore complex server diagnostics, leaving the hardest problems to languish in the queue.
Another dangerous practice is premature closure. An agent might apply a band-aid fix and quickly mark the ticket "Resolved" to beat the SLA clock. The user, realizing the issue is not actually fixed, reopens the ticket a day later. If you do not actively monitor your reopen rates alongside your MTTR, you are flying blind. A plummeting MTTR coupled with a spiking reopen rate means your team is gaming the system, not improving service.
Finally, avoid applying rigid MTTR targets to Major Incidents. When a core database fails, you want engineers focused on systemic stability, data integrity, and root cause analysis. Pressuring them to resolve the issue as fast as possible often leads to hasty patches that cause secondary outages later.
Aligning Your Service Desk Platform With Your Metrics
The right software environment dictates your ability to improve. Relying on basic ticketing instead of exploring modern service desk features like AI-powered triage, agentic auto-resolution, and embedded self-serve search guarantees that you will hit a speed ceiling. Your agents can only type so fast.
Furthermore, restrictive software pricing models actively harm MTTR. When a platform charges per-seat, IT managers often restrict access to core agents to save money. This prevents wider engineering or operations teams from directly accessing tickets, forcing inefficient communication through external channels. A model based on transparent workspace pricing allows broader collaboration across your company, bringing the right experts directly into the platform without penalty.
Lowering your resolution times is not about making your team work harder; it is about systematically removing the administrative friction that prevents them from working at all. To start routing, resolving, and measuring your support requests intelligently, create your QueueDesk workspace and see the difference immediately.
Get started today
Ready to fix internal support?
Free Starter plan. No credit card. Up and running the same day.
Start freeFrequently asked questions
Does MTTR include the time waiting for an employee to reply?+
Not if your SLA rules are configured correctly. By utilizing a 'Pending User' or 'Waiting on Customer' status, you can pause the SLA timer while the ball is in the employee's court, ensuring your agents aren't penalized for slow responses.
Should Service Requests and Incidents share the same MTTR target?+
No. Incidents require immediate triage and rapid fixes because they represent a break in normal service. Service requests (like ordering hardware) involve procurement, approvals, and shipping, requiring a completely separate baseline and expectation.
How do you measure MTTR when a ticket is escalated across multiple internal teams?+
While the overall MTTR spans the entire ticket lifecycle, you should track Operational Level Agreements (OLAs) for each specific group. This allows you to see exactly which team (e.g., Tier 1 Helpdesk vs. Tier 3 Infrastructure) is holding up the resolution.
Does a fast resolution time guarantee high employee satisfaction (CSAT)?+
Absolutely not. A fast MTTR combined with a high reopen rate or low CSAT scores usually indicates that agents are rushing, providing partial fixes, or closing tickets before confirming the user is actually unblocked.